Skip to content

Category: Search and Discovery

The OCLC Kerfuffle: In which I write much but come to few conclusions

I’ve been watching the OCLC policy change discussion unfold slowly over the last few weeks, and I’ve got to say, I’m flummoxed. On the one hand, I don’t like the new license. I agree with most of what’s been written about the potential dangers it poses to innovation and the odd irony that member institutions will pay large sums of money to hand over their data to OCLC so that OCLC can lock it down for them. (I’ve included links to key posts and documents down at the bottom of this post, for those who’d like to catch up.) On the other hand, who am I to claim that OCLC has no right to try to sustain itself financially?

For me, the topic hinges on three main questions:

  • Is this really a change, and if so, how significant of a change is it?
  • What do they really mean by “Reasonable Use”?
  • And what does this mean for those of us that aren’t in the business of creating and maintaining bibliographic systems?

So first of all, is this really a change?

Karen Calhoun of OCLC has written more than once that the new license is just a clarification of the old license and that it serves to protect the community’s investment in the WorldCat records. She commented on Aaron Swartz’s blog post that “the policy carries forward the principles, if not the wording of the current Guidelines, which have been in place since 1987.” Later she wrote on her own blog at length and again asserted:

The difference is not in the principles, then, but the environment in which the principles are applied. The Guidelines [meaning the old policy] came from the limited data sharing environment of the 1980s. The updated policy’s landscape is the Web and the incredibly dynamic data sharing environment it represents. (cite)

In other words, the old policy protected community investment in the cooperative at a time when mass data sharing was not the norm, and the new policy protects that same community investment in the current environment where the default assumption on the web is that if there’s a big pile of data out there, anyone who wants to can play with it and make it work for them.

I have no idea whether the old policy felt restrictive 21 years ago, but I know that the new one feels restrictive now. It seems to me that the paradigm shifted right out from under OCLC and that reinforcing the principles of information sharing from 21 years ago is akin to re-inventing the information searching environment of 10-20 years ago.

It also seems to me that if libraries invest time, effort, and money into building a massive dataset, the best return on that investment would be to have people (OCLC or anyone else) take that data and make it work for us and for our patrons. This is what we do when we invest in the stock market, or even put money into savings accounts. We effectively sign it over to whomever can take it and make it work for us. The way this new policy reads, it feels more like protecting our treasures by tucking them into a safe deposit box. We rent the space and gain no interest, causing our “investment” to depreciate over time.

So maybe we’re just protecting OCLC’s investment in our data. Personally, I’d feel better about the whole thing if they just came out and said that.

What about this “Reasonable Use“ clause?

There’s also one clause in the policy that I find disturbingly vague. It’s the clause that defines “reasonable use,” and serves a very similar function in this license as the Fair Use clause serves in copyright law. Here it is:

13. “Reasonable Use” means Use of WorldCat Records that is reasonable for the intended Non-Commercial Use and consistent with the intent of this Policy. Without limiting the foregoing, the term “Reasonable Use” does not include any Use of WorldCat Records that:

a. discourages the contribution of bibliographic and holdings data to WorldCat, thus damaging OCLC Members’ investment in WorldCat, and/or
b. substantially replicates the function, purpose, and/or size of WorldCat. Please see the FAQ for a discussion of Z39.50 for cataloging using WorldCat-derived bibliographic records.

As Greg Schwartz noted on this week’s Uncontrolled Vocabulary, there are a lot of weasel words here. How big, how related in function, and how related in purpose does a system have to be before it violates this clause? And then there are the conspicuous “and/or” weasel words that leave OCLC room to claim license violation if any part of this clause begins to make them uneasy.

Seems to me that the biggest violator of section 13.b in existence right now is the Library of Congress, and that makes no sense at all. But if you think about it, its catalog is massive and exactly duplicates most of the functions of WorldCat. LibraryThing is also massive, but serves such a completely different purpose that I can’t see how it harms the “investment” of the cooperative. If anything, its giving the cooperative ideas about what might be possible in our own catalogs given the data they produce.

Just as a side note, I wonder if they have to grant Google and other search engines the right to crawl WorldCat.org.

Implications for those us in the public services world?

So what. Why do I care? In my day-to-day work, I search WorldCat when I need it, and I’ll continue to do so. I don’t do cataloging work. I won’t be the one deciding whether or not to put the new field that links to OCLC’s license in our records. And I certainly don’t build discovery systems that would make use of WorldCat records.

Well, I worry about two things. First, that this will stall efforts to invent a discovery system that actually works, and works well — one that patrons are happy to use, and one that puts to good use all of the metadata that catalogers put so much time and effort into creating.

I also worry that this move might implode OCLC. It has the chance to take a hard look at its “principles” and come up with creative ways to position itself as the nexis of all bibliographic data on the web, or it could spark its potential user community to rebell and rebuild elsewhere. My favorite analogy for this comes from Steve Lawson’s blog where he writes:

Coincidentally, I was reading Matthew Battles’ Library: An Unquiet History today and came across this interesting tidbit on page 29 about the Library of Alexandria:

In an effort to stop the growth of the libraries at Rhodes and Pergamum, both of which threatened Alexandria’s preeminence, the city’s rulers banned the export of papyrus. The move backfired, however, spurring the Pergamenes to invent parchment (charta pergamenum), which for its strength and reusability would prove to be the preferred writing medium in Europe for more than a thousand years.

WorldCat has been making great strides forward recently, and I would hate to see it shoot itself in the foot over a piece of papyrus. It also has an incredible treasure trove of information, one that would be a shame to have to duplicate, and one that could yield huge dividends if invested wisely rather than stuffed into a safe deposit box.

Or is this the push we all needed?

For further reading:

3 Comments

Drooling over SOPAC – Wondering about Its Inner Pig

I was going to write about scratch paper today (really, I was), but that can wait for another day. Today I’m thinking about Darien Library, Drupal, and John Blyberg’s SOPAC (Social OPAC).

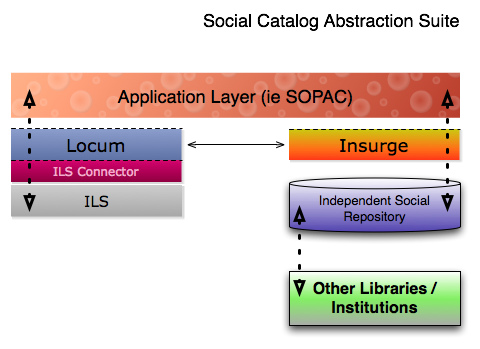
A year and a half ago, when he released the first version of the SOPAC for the Ann Arbor District Library (here’s his blog post), Blyberg’s extensive customizations were definitely cool, definitely innovative, and definitely had potential. He was working hard to put lipstick, a wig, and a dress on his pig. Well, now he’s covered the pig altogether. I won’t get into details (mostly because I only barely understand them myself), but he has coaxed his Drupal-based web site to pull information from their ILS rather than pushing the searcher into the ILS’s environment.

Other people have tried to insert new interfaces between their ILS and their patrons with more or less success, but I think Blyberg has just shown us an example of this type of project that not only works well (drawing on information from the ILS, from a local database of user-generated content, and potentially from a much larger database of user-generated content from other libraries), and is ILS-agnostic, butthat also looks good.

Here’s the diagram he uses to explain where all the information comes from:

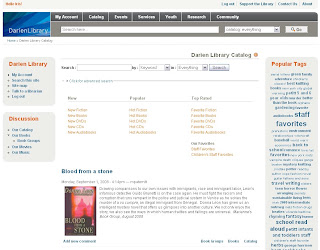
And here’s what the catalog looks like (notice the juicy tags on the left):
When you do a search, results appear in the main content area of this same screen, fully themed to match the site. So beautiful!

To say I’m jealous is an understatement. If we can’t bring ourselves to migrate ILSs, I want something like this. But I do have two reservations: this still requires the discovery layer to harvest and store information from the ILS, and that pig is still under there somewhere. As far as I can tell, the ILS is still locking down untold treasures in the form of data that catalogers have worked so hard to include in our records and it’s preventing us from exploiting that data fully. An actual relational database as the foundation for bibliographic information would make me so very happy. Still, this is really really exciting. I can’t wait to see if other libraries pick up this open source software and continue to develop it further.

Comments closed

Linking to WorldCat in Reference Emails.


So here’s the thing. Like many reference librarians, I use WorldCat all the time. And like many reference librarians, I use the FirstSearch version a lot for advanced features and more seamless integration with our local collections than WorldCat.org can offer. For instance, I love the “Advanced Options” under “More Like This” that lets me pick and choose which parts of the metadata were relevant to me and do a more advanced search on just those elements. And sure, the FirstSearch display is a little overwhelming, but part of what makes FirstSearch good for professionals is the huge amount of information displayed for each record. We’re used to the display, so it’s not a problem for us, and often I skim through all that information and learn a whole lot about an item in a very short amount of time. Besides, my eyes are trained to take in what I want from that interface and leave the rest. I know where on the page the OCLC number lives, for example, so I only look at it if I want to.

One thing it doesn’t do well, though, is let me link to a specific record. I can’t send a link to a student and say “Here, this is the journal I was telling you about.” I can do this at WorldCat.org, though, and that’s a much better interface for students and faculty anyway. I wish there were a “link to this record” in FirstSearch, or at least a “View this record at WorldCat.org,” but since there isn’t, here’s what I do.

  1. Do all my behind-the-scenes advanced searching in FirstSearch (when appropriate).
  2. Find what I’m looking for.
  3. Do a little happy dance in my chair.
  4. Copy the OCLC number.
  5. Open a new tab and click the bookmark I’ve names “WorldCat Link Base.” This contains the base of WorldCat.org’s permanent URL. http://www.worldcat.org/oclc/
  6. Paste the OCLC number onto the end of that URL and hit enter.
  7. Et Voila! Stable URL to the bibliographic record of whatever-it-is I wanted to send to somebody, complete with a friendly interface.

The trick comes when they’re off campus and don’t have pre-loaded links to our Interlibrary Loan system. I wonder if it’d be possible to go through our proxy server for that. If so, I’ll have to change my link base… Hmm…. things to ponder. And wouldn’t it be nice if I knew javascript and could make a bookmarklet that would do that to OCLC numbers for me, and maybe copy the full stable URL to my clipboard?

6 Comments

These are a few of my favorite things

I found myself listing my three favorite e-resources today. Usually I have trouble coming up with my favorite of anything, but these three popped into my head with little effort.

Ulrich’s
I hate trying to figure out where an obscure serial has been indexed, but Ulrich’s makes this easy (most of the time). But even beyond that, I absolutely love it for solving a major problem for my students. For the last two years, I’ve taught this as a cheat sheet of “print sources.” I had the hardest time coming up with an easy way to explain how to tell if what you’ve found online (on the free web or through our bibliographic databases) counts as a “print source” when print vs online is becoming a more and more murky distinction every year, and really makes no sense at all to students (or librarians, really). Students were paralyzed thinking they couldn’t use eJournals because their professors had banned “web sources,” and professors wondered why their students were using out-of-date and only-barely-relevant journal sources in their papers. It was because their poor students had been confining themselves to our print journal collection, which is only a fraction of our total journal collection. So now I get up in front of a class and show them the cheat sheet. If you can find a publication name (and I show them how to hunt one down), look it up in Ulrich’s. If it is listed, it counts as a “print source.” Problem solved.

OED
I love word histories, and this is the most comprehensive dictionary of word histories. Ever. I don’t often have much call to use it in my day-to-day work, but I love it for all those late-night “I wonder when we started using ‘research’ as an intransitive verb” moments I have. It has also solved many a word squabble in my family (which has at least 4 discussions about word usage, etymology, or relationship over the dinner table each week).

MLA International Bibliography
I love this because it’s such a treasure-trove of articles, and (please don’t laugh) because it’s incredibly quirky. I know that we’re supposed to love it when students can use resources on their own. You know… usability and stuff. But this thing is a bear to use well, and I’m pretty comfortable with it, which makes me feel useful. And I love feeling useful.

3 Comments