Skip to content

Category: Services

Data Management and the Humanities

Humanities Data: Document fragments from church archives in Cuba

This morning my colleagues Kristin Partlo and Sarah Calhoun presented with me on data management plans (DMPs). The session itself was mostly a conversation about some example DMPs from the collection of successful DMPs that was recently released by the National Endowment for the Humanities followed by conversations about how we might talk to faculty (using this DMP template as food for thought). But from this conversation a few themes crystalized for me.

Why would humanists care?

I think we often hear that “sharing the stuff of my research with the world” isn’t a huge motivator in the humanities. I’m not sure how broadly true that is, but it’s true enough with enough people that it bears thinking about. And I have heard skepticism, usually in the form of “nobody else will care about this stuff I’ve collected,” so how do we address that?

Sometimes I think maybe it’s a matter of vocabulary, so talking about creating “an archive” or “a digital collection” might capture imaginations where “manage/share your data” won’t. Even talking about how a bibliography is a described dataset can be useful because humanists are very familiar with practices of collecting, organizing, and sharing bibliographic information, usually at the ends of articles, books, and syllabi, but sometimes independently. Humanists have actually been doing data management since forever when you think about bibliographies. In this context, we care about versions (editions), standardized and encoded “data fields” (so that other researchers know if you’re referring to a title of a chapter, article, or book, for example), durable URLs whenever possible… Bibliographies are rich with descriptive and preservationist practices that can help inform management and sharing of files and information more broadly.

I think another aspect of why Humanists might care involves thinking about sharing with the sympathetic collaborator that is your future self. Your future self will forget the ins and outs of where you put or how you named your image files, or what the columns on your spreadsheet actually mean. Our computers are chalk full of the stuff of our research — PDFs, draft versions, images, audio, video. Knowing where all of those things are requires management of all of that data just so that you can find things again later.

Learn through analogy with the known

Kristin talks about how the monograph is largely self-describing. It has title, author, and publisher information in predictable spaces. There’s the table of contents, often an index and bibliography, and things like introductions and conclusions that describe the book for you.

Then there are style guides and formal or informal glossaries that people adopt, and these serve to help make your data (“data” writ large) understandable and consistent for other readers.

These are things that are familiar, so it’s easier to point to these things and remind ourselves that we’ve already seen the usefulness of self-describing units of scholarship and of somewhat standardized best practices. Now we just need to apply it to the digital stuff we’re working with more and more these days.

And in the past, libraries and archives were the main places that managed the sharing of shareable humanities data (primary and secondary sources), but the sharing involved researchers traveling to those collections (humanities “datasets”) to use them. Now individual researchers can create collections, or use collections without physically traveling from dataset to dataset. But this also means that researchers now have more responsibility to do some of the description and standardization that libraries, archives, and publishers formerly did a lot of. So yes, the work feels different, but it’s built on the same principles that humanists already value.

Formal vs informal data management

One of the interesting themes of our session and all the other data-related sessions I attended is that people talk a lot about the data management requirements of grant-funded projects. Meanwhile, I haven’t supported that work at all, but I have helped quite a few people manage their own individual or collaborative non-grant-funded projects. And I really think that data management becomes much more alive and broadly useful if I think about how the best practices identified and codified by grant funding agencies help us think about best practices for regular, every-day digital life, right down to the daily action of naming and putting a file into a folder on my computer. For me and for the people I’ve worked with so far, formal DMPs are alien things that don’t intersect with my life and research. But the spirit and practices reflected in those DMPs? THOSE I care deeply about. So perhaps shifting language from compliance to best practices, and shifting focus from grants to every day organizational practices, perhaps these things can help make data management less of an alien object that only scientists and social scientists ever touch.

Comments closed
Big fun with small data

While I’m on shift this Sunday (during the most glorious fall day we’ve had, on a day that combines Family Weekend and Homecoming Weekend), I played around a bit with our chat reference statistics.

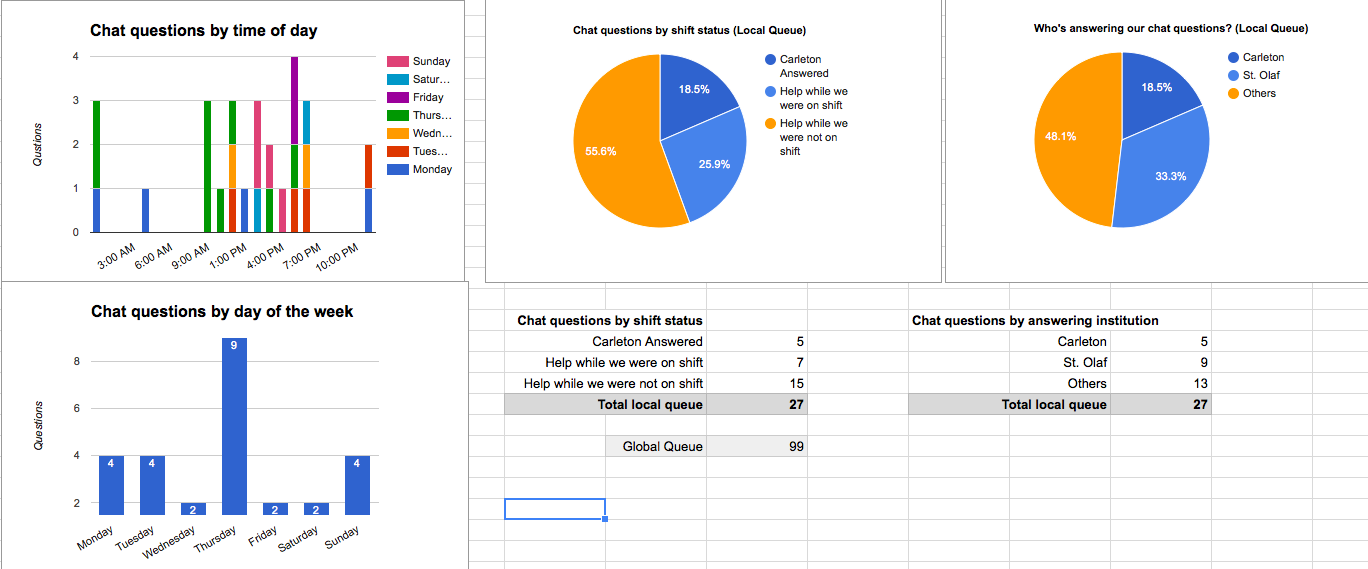
Our students have never really used chat reference much. In part this was our fault (we didn’t have a very friendly chat widget and we didn’t have the unlimited funds needed to have 24/7 reference service) and in part this was because on a small residential campus, the majority of the people who wanted help while we were on staff were already in the library. (That’s what students told us when we asked, and the data from this year bears it out by a slim margin.)  So last year we’d fielded three whole chat reference questions in the first four weeks of school.

This year we’ve switched to QuestionPoint, which means we have 24/7 reference and access to a chat widget that looks a lot more like chat widgets people are used to seeing. Now here’s where the big fun with small data comes in. Because last year’s n was so small, I can say that this year we’ve had a 800% increase in chat questions. Woo!

If we’d changed nothing but the interface, we would likely have answered just the 5 questions that we have answered while on shift this term (66% increase), but the change in librarian coverage has made a huge difference. 15 of this year’s 27 questions were answered while we weren’t on staff, and another 7 question were answered while we were on staff but otherwise occupied. So that’s pretty cool. Usability and coverage FTW!

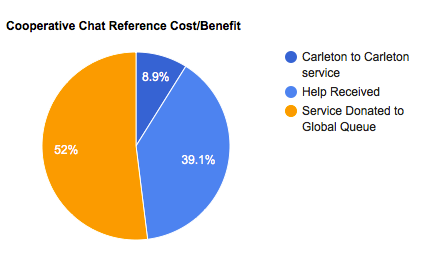
Updated to add: I was curious to see how the service is working from a cost/benefit perspective. We donate a specific number of hours per week based on our FTE, and it looks like the formula is working ok. We have answered 29 questions for other institutions, and between the help the collective has given us us and our own efforts, our patrons have gotten 27 questions answered.

2015-10-11_2246

Comments closed

Leveling Up on Chat Reference

Our library recently joined AskMN, the Minnesota cooperative of OCLC’s global QuestionPoint service. On the one hand, this is extremely exciting. We get to donate a few hours per week to the “global queue,” answering questions that people at other academic institutions ask but whose own librarians are either busy or gone for the day. In return, we get 24/7 chat reference service for our patrons provided by the cooperative. Pretty sweet deal!

On the other hand, the experience of providing chat reference services to people I can’t see at institutions I don’t know has been a nerve-wracking and humbling one for me so far. The institutions in the cooperative leave us a cheat sheet of sorts, so we know their link resolver information, their loan rules, etc, so we’re not totally flying blind, but some schools provide more information than others, and some schools have very few resources available in the first place. So every time I hear that “ding” that tells me there’s a new patron waiting in the queue my heart races a little bit, my hands get a bit sweaty, and I’m thrown right back to my very first days staffing reference desks where every approaching patron was simultaneously a thrill and a terror. Will I be able to figure this out with the patron? Will they lose all respect for me if I take a wrong step along the way? The chances of failure seem so very high. Each success is its own day-making victory. And no matter how many successes I have in a week, they all seem to get categorized in my brain as the exception to the rule that I’ll probably fail the next person.

I’ve tried various strategies during my shifts. “I’ll pick up questions that I pretty much know I’ll be able to answer without trouble” didn’t last long. There aren’t many of those, and I don’t want to be a bad colleague and leave everyone else to answer all the questions while I sit on the side being scared. Also, if you take too much time to read and think about the answer before picking up the question, another librarian will swoop in and get it. Or rather, they’ll pick up the ones you wish you could have picked up while the super convoluted questions sit there and sit there, taunting you, explaining your guilt and fear to you in minute detail.

“I’ll pick up any question, without even looking to see what the question is first” also didn’t last long. Basically, I couldn’t make myself do it more than a couple of times because frankly, I’m not a terrific data librarian and that happened to be the subject of one of the first questions I got under this new resolution. Luckily “refer to patron’s institution” exists in QuestionPoint!

Today as I took what I know about databases in general and how they interact with EndNote and slowly, slowly walked a patron in Connecticut through importing references from a database I don’t have and can’t see into an EndNote installation I also can’t see (we did it! Victory!), I realized three things:

  1. The bedrock basics of reference work is the same — even though I feel more like I’m working alone than I do when I’m at our physical reference desk, and therefore more pressure to get the question answered thoroughly all in one shot, I’m actually still conducting the same pattern of work: “Let me get you started, at least, and then set you up with an expert afterwards if needed.” I need to remember that.
  2. Just like in face-to-face reference, a lot of customer service has to do with being good natured and generally cheerful, even if you have NO idea what’s going on (and it turns out that the patron has been secretly clicking on something you didn’t realize he would click on, especially since you said to click on something else, and THAT’S why he keeps saying he doesn’t see what you’re seeing). I always say my job is about 90% bluff (“SURE I can help you find that thing I’ve never heard of…”). The same is true online. I need to remember that.
  3. I really love face-to-face reference in a library I know well. But I can do it other ways too. I need to remember that.
6 Comments

ILL2.0

So, in the bad old days, we shuttled books and articles back and forth between libraries.

Now, in the days of ILL2.0, where much of our collection is electronic and governed by license agreements, we shuttle people back and forth between libraries. “We’re sorry, you’ll have to actually go to St. Olaf to read that. No, we can’t have them print and send a copy. Yes, I know it’s sitting there online, and we have access to the internet from here, too. And yes, I know we’re a consortium with cooperative borrowing privileges. Even so…”

Awesome.

2 Comments